NVIDIA releases open Nemotron 3.5 Lightning and NeMo Switchyard model router
On 2026-08-11 NVIDIA released Nemotron 3.5 Lightning, an open 30B-parameter (3B active) mixture-of-experts model for long-running agentic workloads that runs on a single laptop/desktop GPU, plus NeMo Switchyard, open software that routes sub-tasks between models. Reports the same week said NVIDIA is training a ~1-trillion-parameter Nemotron 4.
Key facts
- Released 2026-08-11
- Nemotron 3.5 Lightning: 30B-parameter MoE (Hugging Face id NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4)
- NVIDIA claims up to 4x faster output and 30% faster agentic task completion vs models in its class
- NeMo Switchyard routing: frontier accuracy at nearly one-third the task cost of Opus 4.8 alone (NVIDIA)
- Partner results: Ramp cut costs 58% and runtime 33%; Cognition cut mean cost 28%; Boomi 100% domain-routing accuracy
- Runs on RTX PCs, DGX Spark, DGX Station, Jetson; open weights, data and techniques
- Reported (Aug 2026): Nemotron 4 in training, largest version at least 1 trillion parameters, possibly ready late autumn
What happened
NVIDIA shipped Nemotron 3.5 Lightning, an efficiency-focused open MoE model meant to serve as a fast worker inside multi-agent systems, alongside NeMo Switchyard, which decides which model handles each part of a workflow (code review, tool use, alert triage, billing questions). NVIDIA frames this as "systems of models" rather than one giant model.
Why it matters
NVIDIA is now a significant American open-weight model developer; cheap local MoE workers plus routing directly target the cost of long-running agents, which dominate 2026 inference demand.
"3B active" is inferred from the model id suffix A3B. Nemotron 4 details are press reports, not official.
Changelog
- 2026-09-29: created
Videos (1)
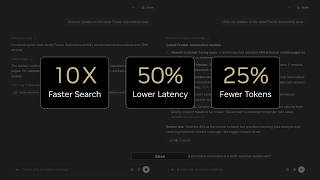
Why AI Agents Need More Than One Model
NVIDIA · 2026-08-11 · officialDescription by Gemini, which watched the video:
Summary
This explainer video from NVIDIA illustrates the "system of models" architecture for enterprise AI agents, focusing on model routing and local specialization. It demonstrates how Glean uses a specialized model (Waldo), post-trained on NVIDIA Nemotron 3 Nano, to retrieve enterprise context and route queries between local and frontier cloud models.
What is shown
- [00:00 - 00:18] Multi-model selectors in various enterprise AI interfaces including Together AI, Perplexity, ChatGPT, Claude, and Glean.
- [00:19 - 00:36] Architecture diagrams demonstrating query routing between local on-premises models and cloud-based frontier models.
- [00:37 - 00:44] Enterprise search demo in Glean querying company policy: "What's our reimbursement policy for home office equipment?"
- [00:45 - 01:28] Workflow schematic detailing Glean's "Waldo" router (post-trained on NVIDIA Nemotron 3 Nano), showing how simple queries are resolved directly via open models while complex tasks are routed to high-parameter frontier reasoning models.
- [01:29 - 01:42] Side-by-side response comparison of "Waldo Off" vs. "Waldo On" for the query "Give me updates on the latest Frasier Automotive issue", showing substantial response time differences.
- [01:43 - 01:53] A multi-step structured reasoning task evaluated in Glean synthesizing company data against public product trends.
Claims & numbers
- Glean's Waldo is post-trained on NVIDIA Nemotron 3 Nano.
- The narrator and on-screen metrics claim that routing with Waldo achieves:
- 10X faster enterprise search.
- 50% lower latency.
- 25% fewer tokens consumed.
- No reduction in answer quality.
Notable quotes
- [00:01] "Intelligence isn't one-size-fits-all. AI agents are built with many models, each bringing different strengths to the work."
- [00:45] "Waldo, a specialized model post-trained on NVIDIA Nemotron 3 Nano, gathers context across sources like support tickets, Slack, and survey data."
- [01:31] "Routing lets Glean search enterprise context 10 times faster. This translates to 50% lower latency and 25% fewer tokens, with no reduction in answer quality."
Assessment
This is an official promotional product showcase and architectural explainer produced by NVIDIA in partnership with Glean. The demonstrated performance enhancements (10x search speed, 50% latency reduction) represent vendor-selected benchmarks shown in a polished, edited UI demonstration.
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.
Related events
Sources (5)
- officialNVIDIA Blog - Nemotron 3.5 Lightning and NeMo Switchyard
- codeHugging Face - NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4
- codeGitHub - NVIDIA-NeMo/Switchyard
- pressCNBC - Nvidia releases Nemotron 3.5 Lightning open-source AI model
- pressTechnology.org - Nvidia is building a 1-trillion-parameter open model called Nemotron 4
id: 2026-08-11-nvidia-nemotron-3-5-lightning · updated 2026-09-29 · open in the interactive timeline